Disclosure: These views are my own and do not represent my current or any former employers. This paper uses public research, standards and product documentation. It does not describe non-public Valve, Steam, Unity or game-studio architecture.
Artifact status: This paper includes a deterministic matched-marginal network benchmark, its configuration, 3,000 model-run records, summary tables and generated SVG figures. The network profiles are synthetic stress models. They are not fitted to production traces and do not estimate Internet conditions, player experience or the behaviour of a named game.
Executive summary
Ping is useful because delay matters. It is incomplete because a mean or percentile does not preserve when delay occurs, how long a bad period lasts or whether several players are impaired together.
Research published on 1 October 2026 made this distinction concrete in networked robotics. Isaac-Net placed a simulated 5G uplink inside massively parallel robot learning. Under load, an independent delay model resampled from the detailed simulator's own delay distribution still produced an Age of Information tail that was about three times too light. Long delays were spread across robots instead of persisting for the same robot.[1]
That result does not establish the same failure in multiplayer games. The Isaac-Net task return did not separate the tested network models. It showed that information freshness changed while the task-level reward remained similar.[1]
The game-networking question is therefore narrower:
If network models have the same per-player delay and loss values, can different temporal and cross-player ordering change predicted gameplay failures?
The accompanying benchmark tests that question with a declared synthetic model.
Each episode contains eight players and 1,024 server ticks at 64 Hz. Every player sends one movement input per tick. Direction changes create input deadlines and scripted close-range shot opportunities. The server applies the newest input it has received.
Every player receives exactly the same network multiset under all three models:
| Outcome | Count per 1,024 packets |
|---|---|
| One-tick delay | 638 |
| Two-tick delay | 240 |
| Three-tick delay | 96 |
| Six-tick delay | 32 |
| Twelve-tick delay | 8 |
| Packet loss | 10 |
This gives a delivered one-way mean of 26.103 ms, a p95 of 46.875 ms, a p99 of 93.750 ms and loss of 0.9766 per cent. Those values are identical under every model.
Only ordering changes:
- the independent model randomly permutes each player's multiset;
- the temporal model clusters values through a synthetic autoregressive process, independently for each player;
- the shared model adds a common process so bad periods align across players.
The standard run uses 1,000 episodes. It produces 3,000 model runs and 8,192,000 player-ticks per model.
The outcome rates changed:
| Measure | Independent | Temporal | Shared |
|---|---|---|---|
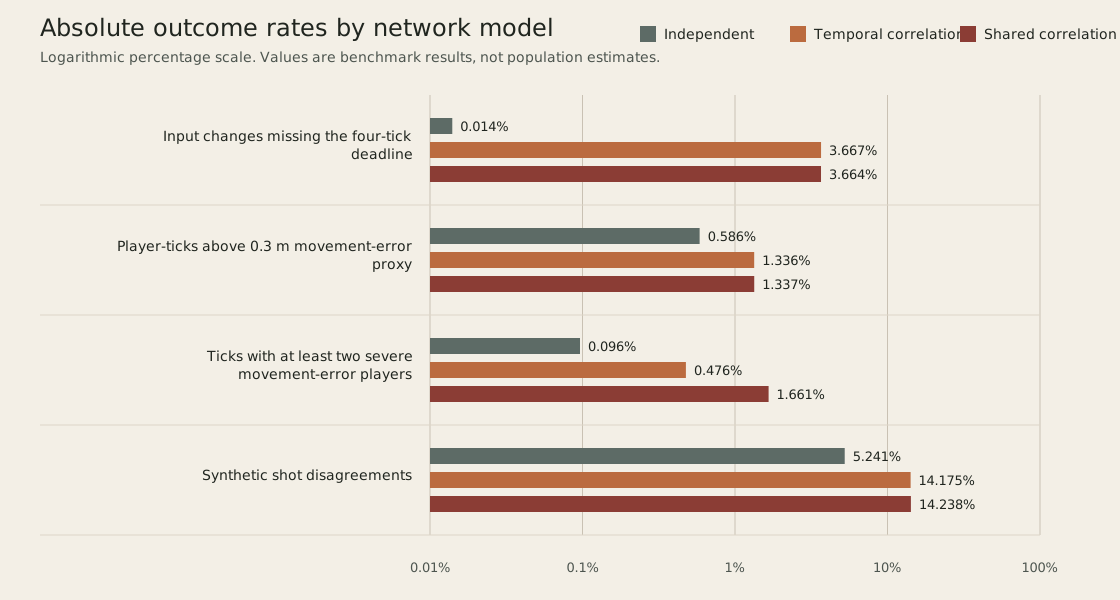
| Input changes missing a 62.5 ms deadline | 0.014% | 3.667% | 3.664% |
| Player-ticks above a 0.3 m movement-error proxy | 0.586% | 1.336% | 1.337% |
| Ticks with at least two severely affected players | 0.096% | 0.476% | 1.661% |
| Synthetic shot disagreements | 5.241% | 14.175% | 14.238% |
| Episode p95 longest severe run | 3 ticks | 16 ticks | 15 ticks |
The independent model usually recovered from a delayed direction change when the next repeated input arrived quickly. The correlated models delayed several consecutive packets. The same high-delay and loss values therefore crossed more input deadlines.
Cross-player correlation changed a different outcome. The temporal and shared models had similar single-player rates. The shared model produced more ticks where at least two players were severely affected at once.
These are properties of the benchmark. The movement-error measure is a local proxy, and the shot test is deliberately simple. Neither represents a production hit-registration implementation. The correlation parameters are sensitivity inputs rather than measured network values.
The result supports a bounded engineering conclusion:
Matching mean delay, delay percentiles and loss rate is insufficient for this multiplayer model. Temporal persistence changes single-player failure tails, while cross-player dependence changes simultaneous impairment.
Modern tools can already represent more than fixed ping. GameNetworkingSockets includes lag, random loss, jitter that can clump packets, reordering and global token-bucket rate limits. Unity supports lag spikes and scripted network scenarios. Linux netem includes correlated delay, Markov loss, Gilbert-Elliott loss and rate controls. ns-3 provides explicit queues and traffic-control models.[10][11][12][13][14]
The practical gap is the test contract.
A multiplayer network test should state which temporal structure it preserves, whether flows share a bottleneck and which gameplay outcome validates the model. Network statistics remain necessary. They should be connected to input deadlines, state disagreement and the mechanics that players actually encounter.
1. Ping is a marginal view
An ordinary multiplayer network report may include round-trip time, jitter and packet loss.
Those measures answer useful questions. They can show that one path is slower, that delay varies or that packets fail to arrive.
They do not preserve the full sequence.
Consider two five-packet one-way delay traces:
Trace A: 20, 20, 20, 20, 120 ms
Trace B: 20, 120, 20, 20, 20 ms
The mean and delay distribution match. The application can still observe a different result if one position in the sequence carries a direction change, a shot or a state transition with a deadline.
Now extend the example:
Trace C: 20, 20, 20, 120, 120, 120, 20, 20 ms
Trace D: 120, 20, 120, 20, 120, 20, 20, 20 ms
The multiset still matches. Trace C creates a longer period where later packets cannot quickly replace stale information.
The difference is temporal dependence.
There is also a cross-player dimension. A household uplink, wireless access point or shared queue may impair several flows together. Per-player delay distributions can look similar while the timing of the bad periods differs.
That timing can affect whether several players miss the same simulation window.
1.1 Loss rate has the same limitation
The IETF documented this issue for loss more than two decades ago.
RFC 3357 defines one-way loss distance and loss period metrics because equal loss rates can produce different application performance. It states that two loss distributions with the same loss rate can produce widely different perceptions for real-time applications.[4]
Ten isolated losses are different from one run of ten losses.
An input stream often repeats current intent, so one isolated loss may be repaired by the next packet without an explicit retransmission. A burst can remove the original update and its replacements.
1.2 Jitter is not one universal number
RFC 5481 distinguishes formulations of packet delay variation and explains that the appropriate measure depends on the task. One use is choosing a de-jitter buffer. Another is inferring queue occupation.[5]
A single standard deviation cannot preserve:
- the run length of high delay;
- the relationship between delay and packet sequence;
- alignment across flows;
- whether traffic changes the queue that creates the delay.
The measurement should match the application decision.
2. Information freshness exposes the missing state
Age of Information measures how old the newest received update is.
For a receiver at time t:
AoI(t) = t - u(t)
where u(t) is the generation time of the newest delivered update.
AoI differs from packet delay. A packet can have a moderate delay while the receiver still holds old information because several newer updates were delayed or lost. The AoI literature developed around status-update systems where freshness matters to a monitor or controller.[3]
Games have the same general concern. A server can be reachable with ordinary average delay while applying an input that no longer represents the player's current action.
The gameplay consequence depends on context.
A stale direction while a player is stationary may have little effect. The same age during rapid movement can produce visible disagreement. A stale target state around a shot can cross a binary decision boundary.
This paper does not define a universal gameplay freshness score. It uses direct outcome proxies with declared thresholds.
3. Isaac-Net provides the catalyst
Isaac-Net was built for a different domain.
The authors study fleets of robots sharing a private 5G uplink. A base station schedules transmissions in 0.5 ms slots. Messages can wait in per-robot queues, and failed transmissions can be retried through HARQ. A robot's delay therefore depends on its own radio state and on traffic from teammates sharing the cell.[1]
The simulator advances thousands of environments on a GPU in lockstep with Isaac Lab physics. Its detailed network state includes scheduling, queues and retransmission timing.[1][2]
The paper also reports its scale boundary. In a validated configuration, the authors report 1,048,576 robots running at 1.24 control steps per second on one GPU, compared with 1.50 without the network. That is 83 per cent of the physics-only rate under the stated random policy.[1]
The model-fidelity result is more relevant here.
3.1 Independent resampling preserved delay values
The researchers compared their per-slot model with simpler alternatives.
One alternative fitted a log-normal delay distribution. Another sampled delays independently from the detailed engine's pooled delays. The second alternative preserved the empirical delay tail while removing dependence between successive messages and between robots.[1]
Under load, the empirical independent model still produced a lighter AoI tail.
The share of robot-steps above the ns-3 AoI threshold was 4.2 to 4.4 per cent for the detailed engine and ns-3. It was 1.3 to 1.4 per cent for the empirical independent model. The paper describes that tail as about three times too light.[1]
The mechanism was measurable. Between 64 and 70 per cent of delay variance lay between robots, while consecutive delays for one robot had correlations from 0.86 to 0.94. A robot experiencing long delays tended to keep experiencing them. Independent draws distributed those delays across the fleet.[1]
3.2 Network fidelity did not change the task return
The task return did not distinguish the network models.
Isaac-Net reports task returns from 81.8 to 82.9 across the tested models, including the ideal link. The authors therefore base the comparison on delay, AoI and messages sent rather than a changed task outcome.[1]
That limit matters.
A more detailed network model can improve a network metric without changing the application decision being studied. Fidelity has a cost. It should be justified by an outcome or policy choice.
This is why the multiplayer benchmark below includes game-sensitive measures rather than stopping at AoI.
4. Existing game test tools are not limited to fixed ping
The strongest version of the original proposal would be too broad.
It would be inaccurate to say that game developers can only test fixed latency, independent jitter and random loss.
Current public tools expose richer controls.
4.1 GameNetworkingSockets includes clumping and rate limits
Valve's open-source GameNetworkingSockets library describes itself as a transport layer for games with reliable and unreliable messages, encryption, packet simulation and detailed statistics.[10]
Its public configuration includes:
- random send and receive loss;
- fixed send and receive lag;
- exponential random jitter with an explicit clumping behaviour;
- packet reordering and duplication;
- global token-bucket send and receive rate limits.[11]
The jitter implementation preserves order by delaying a later packet when necessary. The documentation says this can clump packets. The global rate limiter can create a shared constraint at the library's UDP layer.[11]
Those features are more capable than a single ping slider.
They still leave experimental questions. A test must choose parameter values, decide which connections share the control and determine what outcome constitutes failure.
4.2 Unity supports events and scripted scenarios
Unity's Network Simulator supports packet delay, jitter and loss. It also supports explicit lag spikes, disconnects and scenarios that change network conditions over time.[12]
The presets include a congested home-broadband profile with higher delay and jitter. Custom scenarios can trigger events at specified intervals or change between presets.[12]
This allows temporal structure to be scripted.
The preset label does not establish that the resulting sequence matches a measured household queue. The test still needs a calibration source and an application outcome.
4.3 netem and ns-3 cover a wider model range
Linux netem supports delay distributions, approximate delay correlation, independent loss and stateful loss models. It includes a Gilbert-Elliott option for burst loss, rate emulation and slot behaviour for a crude approximation of bursty media access.[13]
The manual is explicit about limitations. Correlation is approximate, timer granularity affects results and some combinations of queue disciplines may not behave as expected.[13]
ns-3 works at a different level. Its traffic-control layer supports queue disciplines with queues, classes and filters. It records enqueue, dequeue, drop and sojourn-time information. Queue disciplines can represent FIFO service, RED, CoDel and more detailed shared bottlenecks.[14][15][16]
The engineering choice is a model ladder:
| Level | Useful purpose | Main limitation |
|---|---|---|
| Fixed delay | Basic responsiveness and timeout checks | No variation or burst structure |
| Independent marginal model | Broad sampling from a delay and loss distribution | Removes temporal and cross-flow dependence |
| Scripted burst model | Regression tests for lag spikes and loss runs | Parameters may remain synthetic |
| Shared queue model | Contention and cross-traffic tests | More configuration and compute |
| Trace replay | Reproduce an observed sequence | Generalises only as far as the trace population |
| Packet or link simulation | Protocol, queue and scheduler experiments | Highest modelling and validation cost |
The most detailed model is not always the right choice.
The test should use the least expensive model that preserves the behaviour relevant to the decision.
5. Define fidelity through outcomes
Network-model fidelity is often evaluated against network statistics.
That is necessary. A model with the wrong delay distribution is unlikely to predict an application correctly.
It is not sufficient.
A useful evaluation has two layers:
Network fidelity:
Does the model reproduce the network properties it claims to preserve?

Application fidelity:
Does the model reproduce the gameplay outcomes used for an engineering decision?
The second layer prevents a detailed simulator from becoming an end in itself.
5.1 A matched-marginal experiment
The clean test is to hold marginal values constant.
For each player, create one delay and loss multiset. Reorder it under different dependence structures. Run the same gameplay inputs with the same seeds.
This removes the simple explanation that one model is worse because it received more delay or loss.
The remaining difference comes from where those values appear.
5.2 Four kinds of structure
The relevant structure can include:
| Structure | Question |
|---|---|
| Temporal persistence | Does one player's bad period continue across several packets? |
| Cross-player dependence | Do several players enter bad periods together? |
| Closed-loop traffic | Does the application send more or less because of observed delay? |
| Interaction timing | Does impairment overlap a mechanic with a deadline or binary decision? |
The benchmark covers the first, second and fourth rows.
It does not model closed-loop traffic volume. Every player sends one input per tick.
6. Benchmark design
The artifact is named Beyond Ping, with a standard-library runner in run_network_benchmark.py.
The standard command is:
python run_network_benchmark.py
It rewrites the raw run CSV, summaries and figures from network-benchmark.json.
The self-test checks determinism, matched marginals and the intended correlation ordering:
python run_network_benchmark.py --self-test
6.1 Simulation shape
Each episode uses:
| Parameter | Value |
|---|---|
| Players | 8 |
| Server rate | 64 Hz |
| Ticks per episode | 1,024 |
| Episode duration | 16 seconds |
| Episodes | 1,000 |
| Model runs | 3,000 |
| Player-ticks per model | 8,192,000 |
| Movement speed | 6 metres per second |
Players move on one synthetic axis with commands of -1, 0 or 1.
Direction changes occur after a seeded interval from eight to forty ticks. The next command always differs from the previous command. Each player sends the current command every tick.
The server holds the newest command it has received for that player.
Authoritative servers, client-side prediction and reconciliation are established design patterns. The benchmark uses only the hold-latest boundary rather than reproducing a full implementation.[20]
Repeated input lets a later packet repair one isolated delay. A correlated run delays the original update and several replacements.
6.2 Delay and loss multiset
One tick is 15.625 ms.
Each player receives the following exact multiset in every episode and model:
638 x 1 tick
240 x 2 ticks
 96 x 3 ticks
 32 x 6 ticks
  8 x 12 ticks
 10 x loss
Loss remains a separate outcome and is excluded from the delivered-delay mean and percentiles.
The resulting network statistics are:
| Statistic | Value |
|---|---|
| Delivered one-way mean | 26.103 ms |
| Delivered p50 | 15.625 ms |
| Delivered p95 | 46.875 ms |
| Delivered p99 | 93.750 ms |
| Loss | 0.9766% |
These values are identical by construction.
6.3 Network models
The independent model assigns the multiset using a random permutation for each player.
The temporal model generates an autoregressive latent sequence with rho = 0.97 for each player. Delay outcomes are ordered by that latent sequence. High values therefore cluster, while each player retains the exact multiset.
The shared model combines the temporal process with a common latent process using a declared weight of 0.9. This aligns part of the bad periods across players.
The parameters create stress profiles. They are not estimates of a home network, a mobile carrier or Steam Datagram Relay.
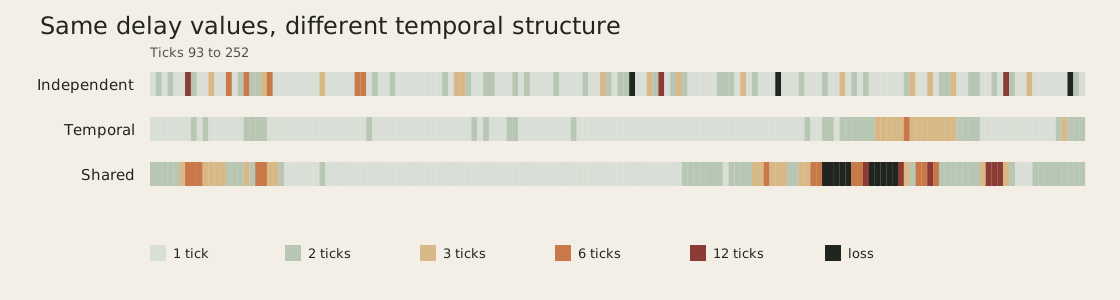
The measured correlation diagnostics confirm the intended difference:
| Model | Mean lag-1 delay correlation | Mean cross-player severe-delay correlation |
|---|---|---|
| Independent | -0.001 | -0.000 |
| Temporal | 0.847 | -0.001 |
| Shared | 0.849 | 0.466 |
The severe-delay indicator covers six-tick delay, twelve-tick delay and loss.
6.4 Input deadline
A direction change is considered on time when the server applies the new command within four ticks.
deadline = 4 / 64 seconds
         = 62.5 ms
The server can satisfy the event with the original change packet or a later packet carrying the same current command.
An event is late when first application occurs after the deadline. It is also late when every relevant packet is lost or superseded before application.
6.5 Movement-error proxy
The benchmark does not claim to reproduce a full reconciliation algorithm.
It calculates a local displacement proxy while server and client commands differ:
E(t) =
    absolute(command_client - command_server)
    * movement_speed
    * tick_duration
    * consecutive_mismatch_ticks
The value resets when both commands match.
This proxy answers a bounded question: how far apart could motion become during the current stale-command run if both states matched when the run began?
A player-tick is severe when the proxy exceeds 0.3 metres.
The measure ignores world collisions, acceleration and server correction policy. It should not be read as final position error in a production engine.
6.6 Synthetic shot disagreement
Each direction change creates one shot opportunity two ticks later.
The synthetic shooter aims at the target's client-side movement state. The server checks its own state at the same tick. The shot is marked as a disagreement when the movement-error proxy exceeds a 0.25 metre hit radius.
This is a decision-boundary probe.
It does not model observer interpolation, weapon spread, lag compensation or a real hitbox. The output shows whether the network ordering moves the declared proxy across one binary threshold.
6.7 Artifact and reproduction
The complete artifact is available as
beyond-ping-benchmark-bundle.zip.
Its current SHA-256 digest is:
7610e93dfd3e83035ac4a32e47d1c28757ac854c5b011db75d45c161ef03214b
The bundle contains:
| Artifact | Purpose |
|---|---|
network-benchmark.json |
Declares every benchmark parameter |
run_network_benchmark.py |
Recreates the CSV and SVG outputs |
network-benchmark-runs.csv |
Preserves all 3,000 model-run records |
network-benchmark-summary.csv |
Provides one aggregate row per model |
network-model-comparison.csv |
Reports the main absolute values and ratios |
matched-delay-trace.csv |
Preserves the full first-episode trace for one player |
network-model-outcomes.svg |
Visualises the absolute outcome rates |
matched-delay-trace.svg |
Visualises one selected matched-marginal window |
Each raw run row records the model version, Python version and canonical configuration SHA-256 digest. The bundle manifest records the size and digest of every payload.
The standard-library runner requires no network access. The raw CSV is the source of truth for the summary and figures.
7. Results
The standard run produced 335,708 input changes and the same number of shot opportunities under each model.
The independent model had 47 late input changes. The temporal model had 12,311. The shared model had 12,301.
The exact rates are:
| Measure | Independent | Temporal | Shared |
|---|---|---|---|
| Input deadline miss | 0.014% | 3.667% | 3.664% |
| Severe movement-error player-tick | 0.586% | 1.336% | 1.337% |
| Two or more severely affected players | 0.096% | 0.476% | 1.661% |
| Synthetic shot disagreement | 5.241% | 14.175% | 14.238% |
7.1 Repeated input repairs isolated delay
The independent model missed 0.014 per cent of direction-change deadlines.
Its rare long delays were normally followed by a shorter delay. A later packet carried the same current movement command and reached the server within four ticks.
The temporal model missed 3.667 per cent.
The delay and loss counts did not change. Long outcomes were placed near other long outcomes. A direction change inside a bad period therefore lost several repair opportunities.
The difference comes from lost repair opportunities.
The independent model had the same delay distribution and loss count. It had shorter runs of bad ordering.
7.2 The tail appears in run length
The episode p95 longest severe movement-error run was:
| Model | Episode p95 longest run |
|---|---|
| Independent | 3 ticks |
| Temporal | 16 ticks |
| Shared | 15 ticks |
At 64 Hz, three ticks are 46.875 ms. Sixteen ticks are 250 ms.
The median episode p95 movement-error proxy was 0.09375 metres under every model. The difference appeared deeper in the tail.
At the episode level, the p95 of the p99 movement-error proxy was 0.1875 metres for independent ordering and 0.375 metres for both correlated models.
This is why average error or one central percentile can miss the failure boundary.
7.3 Shared correlation changes group exposure
Single-player severe movement-error rates were almost identical for temporal and shared correlation:
Temporal: 1.3360%
Shared:   1.3371%
The simultaneous-player measure separated them:
Temporal: 0.4765% of ticks
Shared:   1.6607% of ticks
The shared model had 17,006 ticks with at least two severely affected players. The temporal model had 4,879.
Per-player marginals cannot reveal this distinction.
This matters when a mechanic depends on several participants seeing compatible state during the same short interval.
7.4 The synthetic decision boundary also moved
The independent model produced 17,593 synthetic shot disagreements from 335,708 opportunities.
The temporal model produced 47,588. The shared model produced 47,798.
The disagreement rate moved from 5.241 per cent to about 14.2 per cent.
The absolute values depend on the declared speed, shot timing and hit radius. The useful result is conditional:
Under the same mechanic and exact network marginals, correlation changed how often the movement proxy crossed the hit threshold.
7.5 Information freshness showed the same direction
The median episode p95 AoI was 46.875 ms for all three models.
The tail separated:
| Model | Episode p95 of AoI p99 |
|---|---|
| Independent | 46.875 ms |
| Temporal | 125.000 ms |
| Shared | 140.625 ms |
The central freshness percentile looked equal. The deeper tail carried the model difference.
8. What the result establishes
The benchmark establishes the following within its declared model:
| Evidence held or changed | Observed result |
|---|---|
| Mean delay, p95, p99 and loss held constant | Input-deadline outcomes changed |
| Temporal ordering changed | Severe stale-command runs increased |
| Cross-player alignment changed | Simultaneous impairment increased while the single-player severe rate stayed similar |
| Gameplay mechanic held constant | The synthetic binary shot decision changed |
The result does not establish that every independent impairment model is unsafe.
An independent model may be sufficient when measured traces show weak persistence, when mechanics have wide timing margins or when the netcode absorbs the observed burst lengths.
The test is a method for finding that boundary.
9. A practical network-test contract
A multiplayer test should record more than a preset name.
A useful test contract can include:
| Area | Evidence |
|---|---|
| Network marginal | One-way delay distribution, loss rate, reorder and duplication |
| Temporal structure | Autocorrelation, high-delay run length and loss-period distribution |
| Cross-flow structure | Shared queue, common event or measured flow correlation |
| Traffic shape | Packet size, send rate and application response to congestion |
| Gameplay context | Tick rate, mechanic, deadline and compensation policy |
| Outcome | State disagreement, correction, rollback, underrun or decision mismatch |
| Reproduction | Seed, trace identifier, model version and raw output |
The contract should also say what remains synthetic.
9.1 Start with production evidence
Production traces can provide:
- per-packet send and receive times;
- sequence gaps and loss periods;
- queue or congestion indicators where available;
- connection path and access class;
- application events aligned to the trace.
Collection must respect privacy and retention limits.
The goal is not to publish player identifiers. A trace can be minimised, aggregated or transformed while retaining the timing property needed for a benchmark.
9.2 Preserve a model ladder
One regression suite can use several levels.
Fast independent models remain useful for broad coverage. Scripted bursts can cover known incidents. A shared queue can test household or wireless contention. Trace replay can preserve an observed failure.
The levels should not silently share one label such as "bad network".
Each level has different predictive scope.
9.3 Validate against gameplay outcomes
The network model should predict something the team can observe in a game.
Candidate measures include:
- input application after a declared deadline;
- correction magnitude and duration;
- snapshot-buffer underruns;
- rollback distance or resimulation work;
- client-server decision disagreement;
- simultaneous impairment across interacting players.
The choice depends on the architecture.
A rollback fighting game, an authoritative shooter and a large shared world will not use the same primary outcome.
9.4 Keep deterministic replay
The benchmark fixes gameplay traces and random seeds.
That makes model changes reviewable. A result can be reproduced after a transport change or mechanic adjustment. Raw run data remains the source of truth for the summary and chart.
Determinism does not make synthetic assumptions correct.
It makes their consequence inspectable.
10. Network sensitivity is partly a game-mechanic property
The same network trace can matter differently after a design change.
Movement speed changes how quickly stale input becomes spatial disagreement. Hit radius changes the decision boundary. A longer animation can create more compensation time. A short dash can concentrate a large state change inside a few ticks.
The benchmark makes this dependency explicit:
movement-error proxy
    proportional to movement speed
    proportional to command difference
    proportional to stale-command run length
A faster mechanic raises the proxy without changing the network.
This creates a useful design test:
Does a mechanic remain inside its declared network tolerance under traces the product expects to support?
The answer can guide a mechanic, a compensation policy or a supported-network boundary.
It should not be used to hide a networking defect by making every mechanic slower.
11. Fairness requires more evidence
Network latency can affect competitive fairness.
Research has studied latency balancing and compensation for many years. A 2022 survey reviewed more than eighty latency-compensation papers and organised eleven base techniques into four groups.[6] Earlier work evaluated automated latency balancing for multiplayer games.[17]
Results vary with the mechanic and experimental setup. A controlled Unreal Tournament 2003 study found that typical observed loss ranges had no measured effect on performance or reported gameplay quality in its tests.[7] Other work frames latency sensitivity through the precision a game requires and the deadline available for an action.[18] Cooperative games can also propagate one player's lag into another player's experience.[19]
That variation is a reason to validate a network model against a named mechanic rather than assume one universal threshold.
The 2026 adaptive-time-delay study provides recent player evidence. Across three studies, the authors report that adaptive delay improved average experience compared with fixed delay while preserving similar fairness in the tested two-player conditions. The benefit was clearest above 100 ms. The paper also states that its fixed-latency conditions did not vary over time, which leaves burst and correlation behaviour for later work.[9]
Other research shows that temporal structure can matter to people and tasks. A collaborative virtual-environment study found that large latency significantly affected reported experience without a significant task-performance effect in its setting. Packet bursts had a larger impact on both experience and task performance.[8]
The benchmark in this paper has no participants.
It cannot establish unfairness.
It identifies conditions under which players could receive different or simultaneously degraded authoritative treatment. A fairness claim would require a defined policy, representative traces and player or production outcome evidence.
12. The strongest counterargument
The correlation profile is deliberately strong.
An autoregressive coefficient of 0.97 creates persistent periods. The shared weight of 0.9 creates visible alignment across players. Neither value was fitted to a game population.
The objection narrows the result to a sensitivity test. It shows that a sufficiently correlated synthetic model differs from an independent model.
That objection is valid.
The paper does not recommend shipping these parameters as a universal preset. It uses them to test whether the modelling dimension can affect the outcome while marginals remain fixed. The next empirical step is calibration against representative traces.
There is a second objection.
Production netcode may repair these conditions more effectively than the benchmark. Input bundling, rollback, interpolation and server reconciliation can reduce or move the failure.[6][20] The benchmark's hold-latest server and movement proxy are intentionally small.
That also limits the result.
The artifact is a reference experiment for model comparison. An engine team should replace its gameplay layer with its own deterministic replay and telemetry.
The final objection concerns complexity.
A detailed packet simulator can create false confidence if its topology, cross-traffic or radio parameters are invented. A simpler trace replay may be more defensible. Model sophistication is not evidence by itself.
Calibration and outcome validation remain the deciding tests.
13. Evidence still needed
The next research stage should use measured traces.
A useful study would collect consented, minimised packet timing from several access types and household conditions. It would retain enough sequence information to calculate delay runs, loss periods and cross-flow alignment.
The study should then:
- fit an independent marginal model;
- fit a temporal model;
- construct a shared-queue or common-state model where supported;
- replay the same deterministic encounters;
- compare each model with held-out traces on gameplay outcomes.
The primary outcome should be registered before model tuning.
One useful test is model selection. If the independent model and trace replay choose the same netcode policy across held-out scenarios, the simpler model may be sufficient. If they choose different policies, the modelling difference has an engineering consequence.
14. What this paper does not claim
This paper does not claim:
- that the benchmark represents Steam, GameNetworkingSockets, Unity Transport or a commercial game;
- that
rho = 0.97or a shared weight of0.9describes a real player population; - that the synthetic shot measure is production hit registration;
- that the reported rates estimate player experience or competitive fairness;
- that every game needs packet-level simulation;
- that aggregate latency, jitter and loss metrics are unimportant;
- that no earlier system has combined similar ideas;
- that more detailed simulation is automatically more accurate.
It shows one reproducible matched-marginal comparison and defines the evidence needed to move beyond it.
Conclusion
Ping remains a useful measurement.
It cannot describe whether bad delay persists for one player or arrives for several players together.
Isaac-Net demonstrated the same general problem in a robot control loop. Independent delay draws preserved an empirical delay distribution while producing an AoI tail that was too light under load.[1]
The multiplayer benchmark extends the question to declared gameplay-sensitive outcomes.
Every model received the same mean delay, p95, p99 and loss. Temporal correlation raised the input-deadline miss rate from 0.014 per cent to 3.667 per cent. It raised synthetic shot disagreement from 5.241 per cent to about 14.2 per cent.
Cross-player correlation changed the group result. Ticks with at least two severely affected players rose from 0.476 per cent under the temporal model to 1.661 per cent under the shared model.
These values belong to a synthetic stress test. They are not production estimates.
The engineering conclusion is narrower:
Multiplayer network models should be evaluated by the temporal and cross-player structure they preserve, then validated against gameplay outcomes.
Current tools can express many of these conditions. The missing discipline is to connect a network profile to measured traces, deterministic gameplay replay and a decision the team needs to make.
The sequence is part of the network evidence.
About the author
Jason Doyle writes about reliable software, observability, incident leadership, applied AI and practical controls for systems that influence human and organisational decisions. He publishes at jasondoyle.ie and can be contacted at [email protected].
References
- Zifan Zhang, Mingzhe Han, Kannan Athreya and Yuchen Liu, Network-in-the-Loop at Scale: GPU-Batched 5G Simulation for Massively Parallel Robot Learning, arXiv:2610.02370, 1 October 2026, https://arxiv.org/abs/2610.02370.
- Zifan Zhang et al., Isaac-Net, version 0.2.0, released 5 October 2026, BSD-3-Clause, https://github.com/ZzZTripleZzZ/isaac-net.
- Roy D. Yates, Yin Sun, D. Richard Brown III, Sanjit K. Kaul, Eytan Modiano and Sennur Ulukus, Age of Information: An Introduction and Survey, IEEE Journal on Selected Areas in Communications, volume 39, issue 5, 2021, pages 1183-1210, DOI 10.1109/JSAC.2021.3065072, https://doi.org/10.1109/JSAC.2021.3065072.
- R. Koodli and R. Ravikanth, One-way Loss Pattern Sample Metrics, RFC 3357, August 2002, https://www.rfc-editor.org/rfc/rfc3357.html.
- Al Morton and Benoit Claise, Packet Delay Variation Applicability Statement, RFC 5481, March 2009, https://www.rfc-editor.org/rfc/rfc5481.html.
- Shengmei Liu, Xiaokun Xu and Mark Claypool, A Survey and Taxonomy of Latency Compensation Techniques for Network Computer Games, ACM Computing Surveys, volume 54, issue 11s, 2022, pages 1-34, DOI 10.1145/3519023, https://doi.org/10.1145/3519023.
- Tom Beigbeder et al., The Effects of Loss and Latency on User Performance in Unreal Tournament 2003, NetGames 2004, pages 144-151, DOI 10.1145/1016540.1016556, https://doi.org/10.1145/1016540.1016556, project page https://web.cs.wpi.edu/~claypool/papers/ut2003/.
- Nicholas Milef, Adam Ryason, Di Qi, Samuel O. Alfred, Cullen D. Jackson and Suvranu De, Disruptions to Shared Mental Models from Poor Quality of Service in Collaborative Virtual Environments, Scientific Reports, volume 11, 2021, DOI 10.1038/s41598-021-02567-7, https://doi.org/10.1038/s41598-021-02567-7.
- Samin Shahriar Tokey, Ben Boudaoud, Josef Spjut and Mark Claypool, Adaptive Time Delay for Improving Player Experience and Fairness in First-Person Shooter Games with Network Latency, Foundations of Digital Games 2026, 10 August 2026, https://research.nvidia.com/publication/2026-08_adaptive-time-delay-improving-player-experience-and-fairness-first-person.
- Valve Corporation, GameNetworkingSockets, accessed 12 October 2026, https://github.com/ValveSoftware/GameNetworkingSockets.
- Valve Corporation, GameNetworkingSockets network-condition configuration, commit d534c19,
steamnetworkingtypes.h, accessed 12 October 2026, https://github.com/ValveSoftware/GameNetworkingSockets/blob/d534c19aa760df3fb75fd20db13ba1932b8a5463/include/steam/steamnetworkingtypes.h#L1414-L1508. - Unity Technologies, Network Simulator, Multiplayer Tools 2.2 documentation, accessed 12 October 2026, https://docs.unity3d.com/Packages/[email protected]/manual/network-simulator.html.
- iproute2 project, tc-netem(8), Linux manual page, upstream snapshot 4 August 2026, https://man7.org/linux/man-pages/man8/tc-netem.8.html.
- ns-3 Project, Queue Disciplines, ns-3 model documentation release 3.46, accessed 12 October 2026, https://www.nsnam.org/docs/release/3.46/models/html/queue-discs.html.
- ns-3 Project, Random Early Detection, ns-3 model documentation release 3.46, accessed 12 October 2026, https://www.nsnam.org/docs/release/3.46/models/html/red.html.
- ns-3 Project, CoDel Queue Disc, ns-3 model documentation release 3.46, accessed 12 October 2026, https://www.nsnam.org/docs/release/3.46/models/html/codel.html.
- Sebastian Zander, Ian Leeder and Grenville Armitage, Achieving Fairness in Multiplayer Network Games through Automated Latency Balancing, ACE 2005, pages 117-124, DOI 10.1145/1178477.1178493, https://doi.org/10.1145/1178477.1178493.
- Mark Claypool and Kajal Claypool, Latency Can Kill: Precision and Deadline in Online Games, MMSys 2010, pages 215-222, DOI 10.1145/1730836.1730863, https://doi.org/10.1145/1730836.1730863.
- Eben Howard, Clint Cooper, Mike P. Wittie, Steven Swinford and Qing Yang, Cascading Impact of Lag on Quality of Experience in Cooperative Multiplayer Games, NetGames 2014, pages 1-6, DOI 10.1109/NetGames.2014.7008965, https://doi.org/10.1109/NetGames.2014.7008965.
- Gabriel Gambetta, Client-Side Prediction and Server Reconciliation, accessed 12 October 2026, https://www.gabrielgambetta.com/client-side-prediction-server-reconciliation.html.